astro-llms
Content-collection-first llms.txt for Astro
- TypeScript
- Astro
- Zod
An Astro integration that generates curated llms.txt agent surfaces and per-entry Markdown mirrors from your Content Layer collections. No HTML scraping, no Starlight lock-in.
Problem
llms.txt is becoming the standard way AI agents discover site content, but existing Astro integrations either target Starlight only or scrape rendered HTML and reverse-engineer markdown. Content authors already have structured collections and frontmatter; throwing that away at build time is wasteful and error-prone.
Approach
astro-llms is a build-time Astro integration that reads collections through the Content Layer API. Index metadata comes from frontmatter (with optional llm, llmSection, and llmDescription fields via a shared Zod schema). Body content is taken from the original Markdown sources. Drafts, private entries, and llm: false are excluded. Peer dependencies are Astro and Zod only.
Setup is three steps: spread llmFields into collection schemas, add llmsTxt({...}) to astro.config, and build. Output is /llms.txt, optional /llms-full.txt, and per-entry mirrors under /llms/{collection}/{id}.md.
Outcome
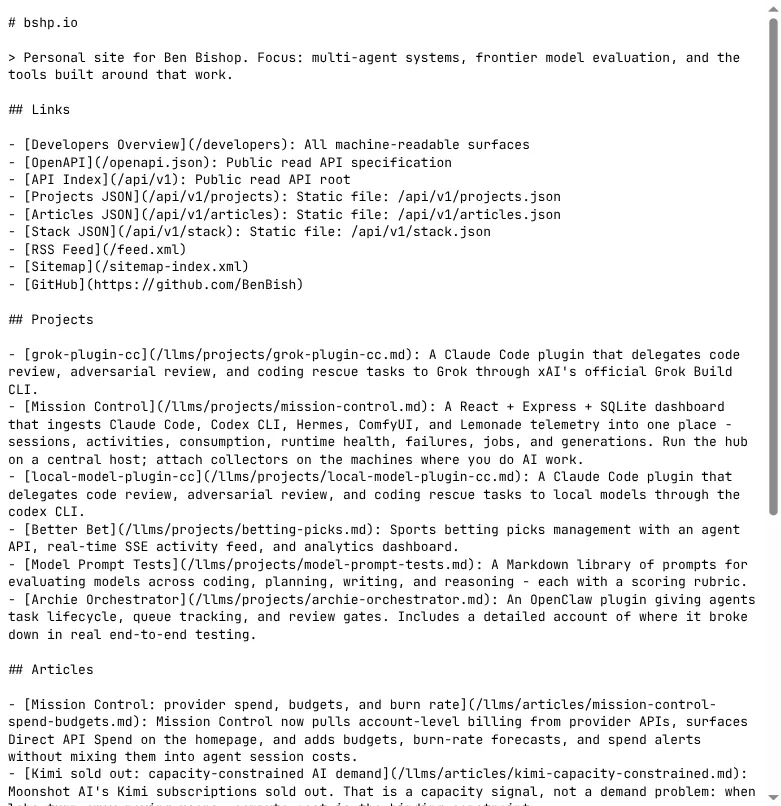
A small npm package that turns content collections into agent-readable surfaces without HTML scraping. This site (bshp.io) generates its own llms.txt with the same package.
Architecture
Astro integration hook runs at build time against configured collections. Zod-validated frontmatter drives inclusion and index copy; source Markdown becomes mirror bodies. Follows the llms.txt specification (H1, blockquote summary, H2 sections, linked list items).