Grok Imagine: a small hands-on image review
I wanted a straight answer for this site: is Grok Imagine good enough for decorative images and quick variants, or is it still only useful for throwaway mood boards?
So I ran a small hands-on check on 2026-08-13: two creates and two single-image edits through the Grok Build image_gen and image_edit tools. Not a leaderboard. Not a free-tier audit. Four calls, two subjects, two styles, with the outputs kept so you can judge them yourself.
Decision
Grok Imagine is a solid option for decorative images and quick variants. In this sample, both generated images were usable and both edits preserved the source composition well.
That is enough for me to keep using it for low-risk asset experiments on bshp. It is not enough to make it the default image path for everything. Exact text, real charts, product UI, and other factual graphics stay code-first or use screenshots of the real product.
What I ran
- Create a 16:9 photoreal laptop and analytics dashboard scene.
- Create a square geometric neural-network illustration.
- Edit the dashboard scene to warm amber light and add a white coffee cup.
- Edit the illustration to replace cobalt accents with emerald and warm the paper slightly.
Each result completed in roughly 10-25 seconds by wall-clock observation. That is interactive, not a controlled latency benchmark. I did not record seeds because the tool surface did not expose them.
Create: dashboard scene
Prompt:
Photoreal laptop analytics dashboard on a desk, soft cobalt ambient light, no readable logos, 16:9.
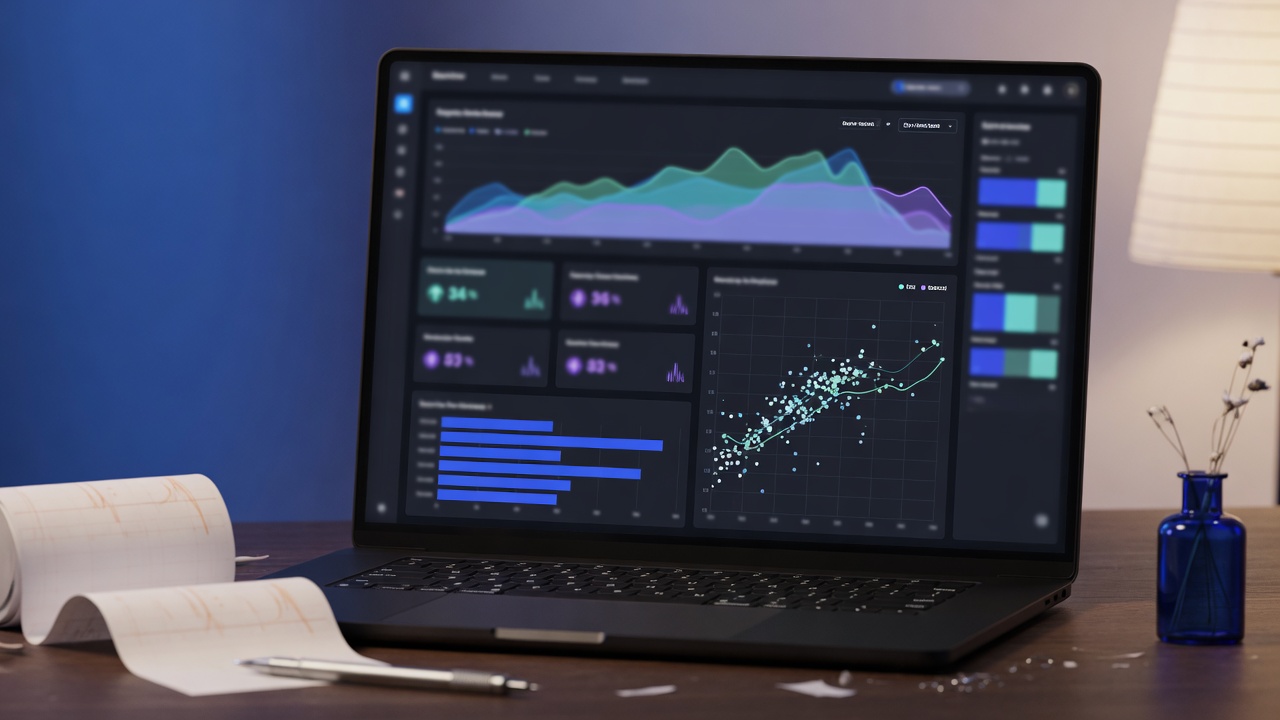
C1. Original create. 1280x720, about 176 KB.
The laptop, desk props, lighting, and dashboard chrome look convincing at article size. The screen still contains invented interface text and values, so this works as mood photography, not as a product screenshot.
Edit: dashboard scene
Prompt:
Keep the composition. Shift the ambient light to warm amber. Add a white coffee cup near the keyboard. Leave the dashboard layout unchanged.
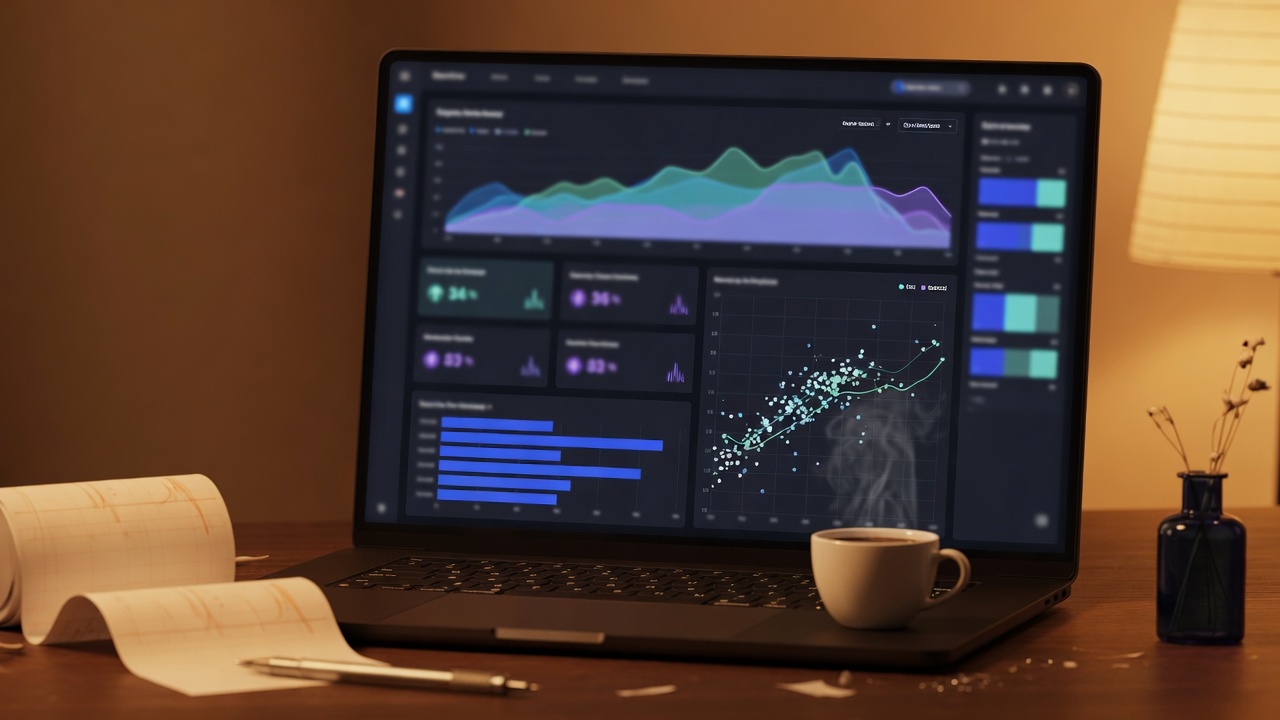
E1. Single-image edit of C1. 1280x720.
The lighting and cup landed. Laptop position, dashboard sections, charts, paper, pen, and vase stayed recognisably consistent. Some pixels across the scene shifted with the new grade, so this is good composition preservation rather than a strictly local or pixel-identical edit.
Create: node illustration
Prompt:
Flat geometric neural-network nodes on warm paper, cobalt accents, no text, 1:1.
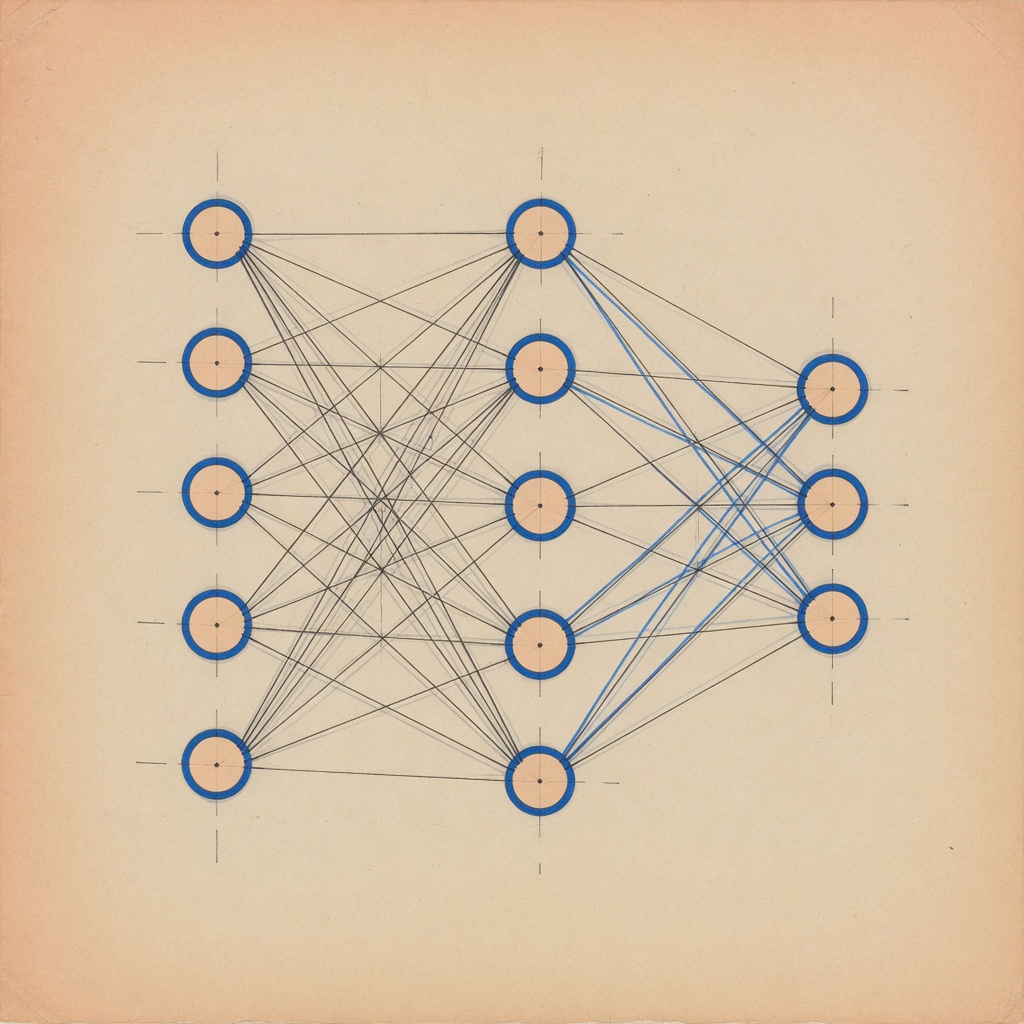
C2. Original create. 1024x1024, about 343 KB.
Coherent paper texture, clean rings, no accidental lettering. The network itself is decorative rather than technically meaningful.
Edit: node illustration
Prompt:
Keep the layout. Recolour cobalt accents to emerald. Make the paper slightly warmer. Add no text.
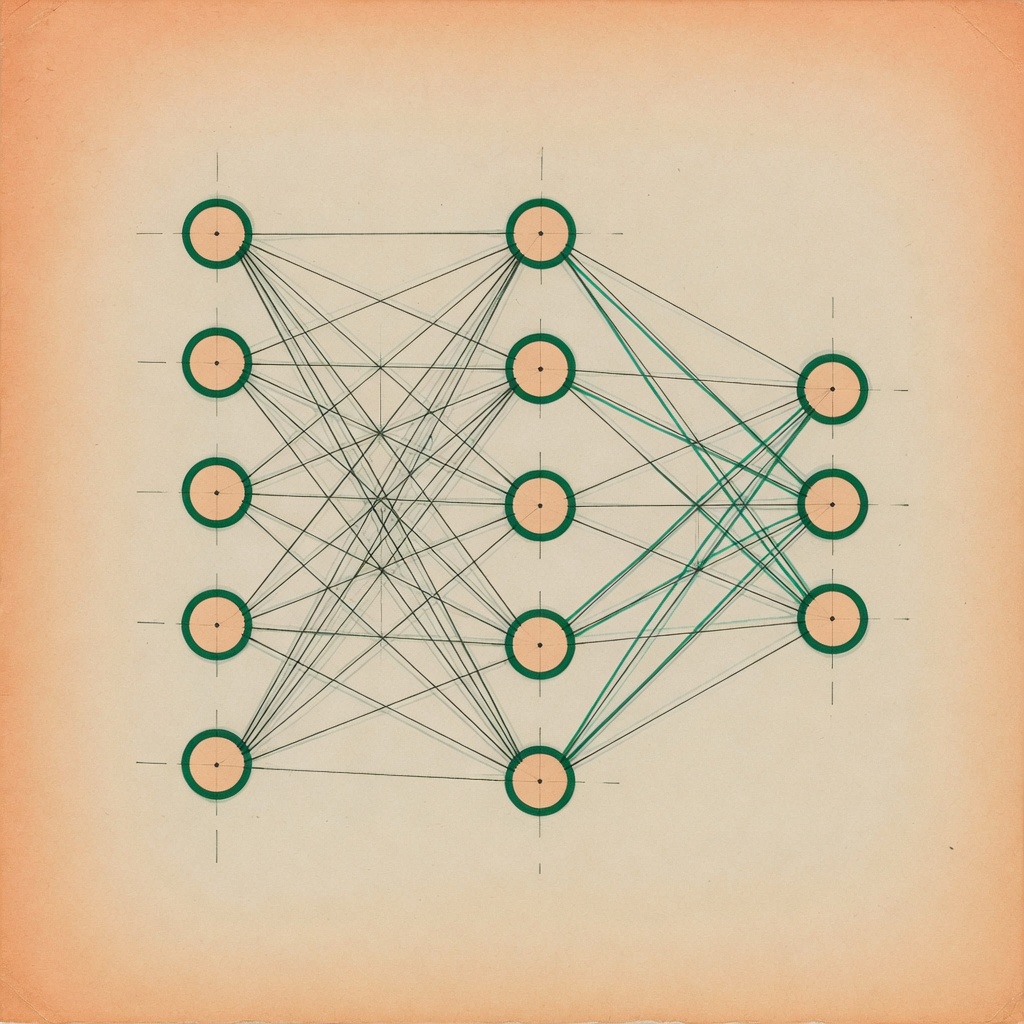
E2. Single-image edit of C2. 1024x1024.
Node positions and line structure held while blue accents went green. The warmer paper treatment landed without restyling the whole piece. This was the cleanest result in the set.
What that means for create and edit
Create. Both styles were usable without another generation. The desk scene looks polished at a glance. The flat illustration avoids the stray letters that often kill generated technical art. This test deliberately avoided exact copy, so it does not support claims about reliable text, metrics, charts, or labelled diagrams.
Edit. Both edits followed the instruction and kept the main composition. The global recolour was especially clean. Object insertion worked too, though the lighting change necessarily affected most of the frame. That supports using edit for colour and mood variants before regenerating from scratch. It does not prove region-edit accuracy, identity consistency, multi-image compositing, or resilience across long edit chains.
Dimensions and speed. 16:9 came out 1280x720. Square came out 1024x1024. All four calls finished in roughly 10-25 seconds. No rate-limit error in this short session.
Product and API notes
The hands-on results came from Grok Build tools. A tool name does not prove the exact backend model revision, so I am not claiming these four outputs came from a separately identifiable API model string.
As checked on 2026-08-13, the current xAI Imagine documentation lists:
grok-imagine-image-qualityfor image generation and editing- Configurable aspect ratio and 1K or 2K output
- Up to three reference images for multi-image editing
- Flat per-image API pricing, with edits billed for input and output
xAI’s Quality Mode announcement describes stronger realism, text rendering, and creative control. Those are vendor claims. This review only independently checked the four create and edit cases above.
Consumer promotions and free limits change. Browser access is fine for experimentation. I would not treat it as a dependable CI or publishing dependency.
When I would use it
I will use Grok Imagine as a preferred candidate for:
- Decorative article and project-card art
- Mood photography where invented details cannot mislead readers
- Colour, lighting, and composition variants of existing decorative assets
I will keep HTML, CSS, SVG, or real screenshots for:
- Product interfaces
- Exact labels and typography
- Charts, metrics, and diagrams that claim to represent real data
- Brand assets that need precise geometry
I am not making Imagine the default for every image job in the repo from this sample alone. That decision needs a broader comparison: repeated generations, typography, people and hands, region-only edits, multiple references, and longer edit chains.
Limits of this review
- Four calls from one session, no repeated prompt trials
- Two subjects and two visual styles
- Single-image edits only
- No masked or consumer-UI region editing
- No multi-image editing
- No exact-text test
- No people, faces, or hands
- No quality comparison with another image model
- Approximate rather than instrumented latency
Directional, not definitive. The samples still stand on their own.
What I would run next
- A larger comparison with at least three outputs per prompt, including failures.
- Exact text, people and hands, region-only edits, multi-reference compositing, and a three-step edit chain.
- The same prompt set against one competing image model before picking a default.
- For missing project screenshots, stylised placeholders only. Prefer real captures for live products.
If you re-run this kind of check, record date, surface, displayed model name, full prompt, aspect ratio, resolution, source assets, elapsed time, attempt number, and unselected outputs. Keep originals beside edits so composition drift is obvious.
Internal spike notes live in the repo at docs/spikes/grok-imagine.md. Sample files for this post are under public/articles/grok-imagine/.