astro-llms: llms.txt from Astro content collections
Agents are getting better at reading the open web, but HTML is a terrible contract for them. Layout chrome, nav, and presentational markup drown out the prose you actually want a model to use. llms.txt is a small convention for fixing that: a plain-text index at a known path, plus optional full-text or per-page mirrors in Markdown.
I wanted that for sites built with Astro content collections. Existing options either target Starlight or scrape the rendered site and convert HTML back into markdown. Both miss the point if your source of truth is already Markdown with structured frontmatter.
astro-llms is a content-collection-first Astro integration. It reads collections through the Content Layer API at build time, writes a curated /llms.txt, and optionally emits per-entry Markdown mirrors. This site runs it in production.
The problem it solves
If you maintain an Astro blog or docs site, you already decided what is public, what is draft, and how each entry should be summarized. That lives in frontmatter and collection schemas. Scraping /blog/my-post throws that away, then tries to recover structure from the layout.
Starlight-specific generators are fine if you use Starlight. They are not a general answer for portfolio sites, custom blogs, or multi-collection content setups.
What I wanted instead:
- Index metadata from frontmatter (curated titles and descriptions, not inferred from the first paragraph of rendered HTML)
- Body content from the original Markdown files
- Explicit exclusion of drafts, private work, and entries marked off for agents
- No runtime dependencies beyond Astro and Zod
What you get
On build, the integration can produce:
/llms.txt- site name, short summary, H2 sections, and linked entries/llms/{collection}/{id}.md- per-entry mirrors with frontmatter and source body- optional
/llms-full.txtwhenfullText: true
Here is what bshp.io’s index looks like after a build:
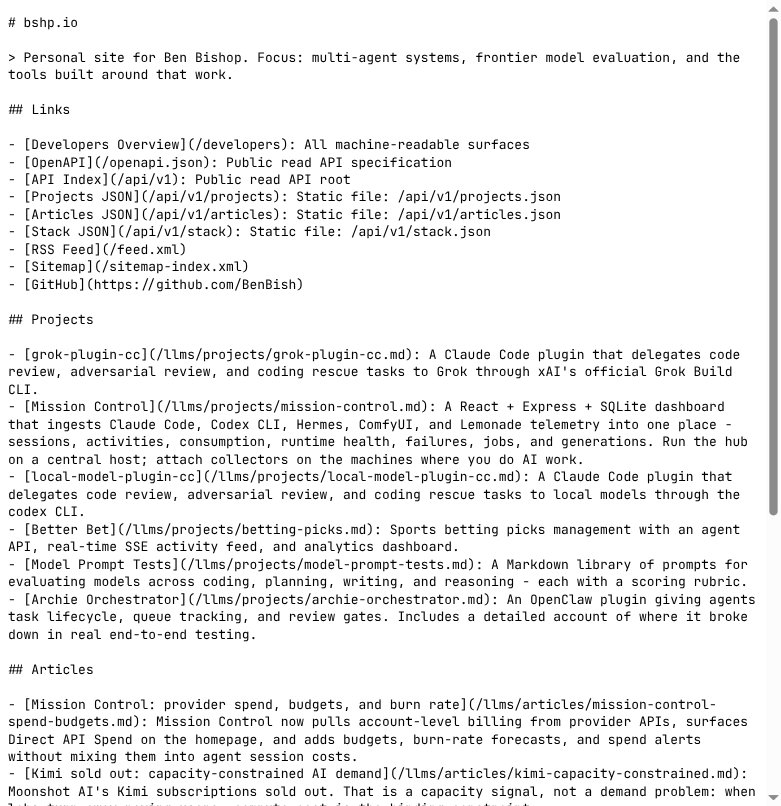
Agents that respect llms.txt start at the index, then fetch only the mirrors they need.
Quick start
Install the package (peer deps: Astro 7+, Zod 4+):
npm i astro-llmsSpread the shared frontmatter fields into each collection you want in the agent surface:
// src/content.config.ts
import { defineCollection, z } from "astro:content";
import { glob } from "astro/loaders";
import { llmFields } from "astro-llms";

const articles = defineCollection({
  loader: glob({ pattern: "**/*.{md,mdx}", base: "./src/content/articles" }),
  schema: z.object({
    title: z.string(),
    description: z.string(),
    date: z.string(),
    ...llmFields,
  }),
});

export const collections = { articles };
Wire the integration in astro.config:
// astro.config.mjs
import { defineConfig } from "astro/config";
import { llmsTxt } from "astro-llms";

export default defineConfig({
  integrations: [
    llmsTxt({
      siteName: "My Blog",
      description: "Notes on distributed systems and tooling.",
      collections: [{ name: "articles" }],
    }),
  ],
});
By default entries are opt-in (defaultInclude: false). Mark them with llm: true, or set defaultInclude: true if the whole collection should appear. You can still set llm: false on a single entry to keep it out.
---
title: "Building a Router from Scratch"
description: "How I built a URL router in Go without any libraries."
date: "2026-07-01"
llm: true
---
Build as usual. The files land in the static output next to everything else Astro already emits.
Configuration worth knowing
| Option | Default | Role |
|---|---|---|
siteName |
required | H1 in llms.txt |
description |
optional | Blockquote under the H1 |
collections |
required | Which collections, and optional section titles |
defaultInclude |
false |
Include all entries without llm: true |
manualLinks |
[] |
Extra index links (API docs, RSS, GitHub) |
mirrorsPath |
"/llms/" |
Where per-entry .md mirrors go |
fullText |
false |
Also emit /llms-full.txt |
mdxPolicy |
"skip" |
Skip MDX or include raw source |
Per-entry frontmatter: llm, llmSection (override which H2 section), llmDescription (override the index blurb).
Multi-collection sites can group writing and projects under different H2 headings and still share one index file. That is how this site is set up: Projects, Articles, plus manual links for the JSON API, OpenAPI, and RSS.
How agents use the output
The llms.txt shape is intentionally boring:
# My Site

> A short description of the site.

## Writing

- [Post Title](/llms/articles/building-a-router-from-scratch.md): Description from frontmatter
A coding agent or research tool hits /llms.txt, decides which links matter, then loads those Markdown mirrors. Because the mirrors are source-faithful, citations and summaries stay closer to what you published than a scrape of the themed HTML page.
Why I published it
bshp.io needed an agent surface that matched how the site is actually authored: Content Layer collections, Zod schemas, static build. Scraping my own HTML to reconstruct Markdown I already had on disk felt backwards. The integration is small enough to reason about, and it is the same package this site depends on in package.json.
If you run Astro with content collections and care about how models discover your writing, try it:
- GitHub: BenBish/astro-llms
- Install:
npm i astro-llms - Live example: bshp.io/llms.txt
Issues and PRs welcome if your collection layout needs something the current options do not cover.